The problem
Imagine you write: “send the address of the restaurant for my Friday dinner to all the guests”. To get there, you have to read your calendar, find the dinner, pull out the location, look up each guest in your contacts, then prepare an email. Five actions, three services.
Handing all of that in one block to a single language model, with every tool in front of it, works badly. The more tools it sees, the more it hesitates and the more often it picks the wrong one. Each call costs more. And when it fails, there's no way to know where.
What I wanted
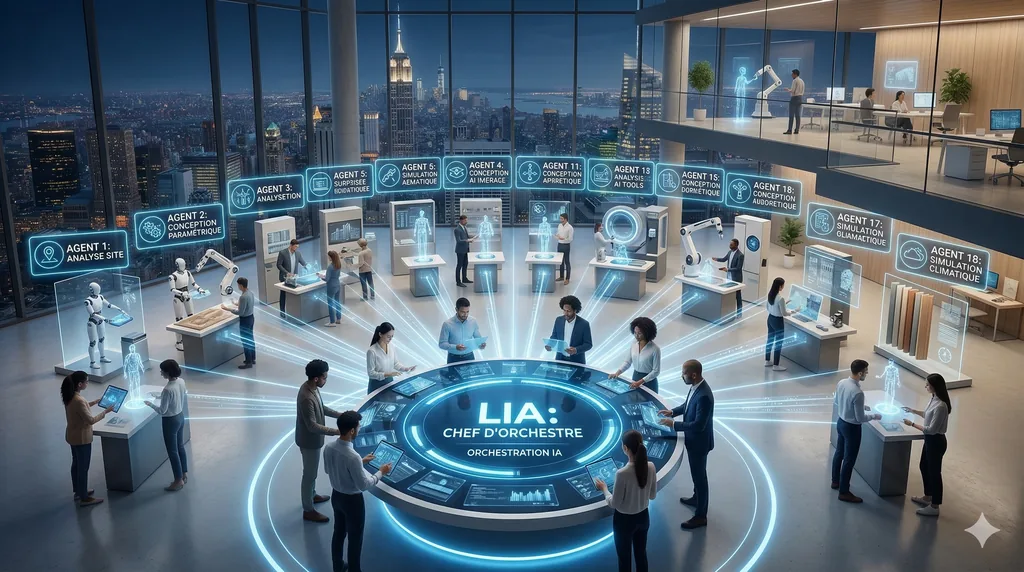
I wanted LIA to work like a small, well-organized team: someone sorts the request, someone prepares the plan, someone checks it, someone carries it out, and someone answers you. Each role does one thing. Around them, each domain brings its own tools and their instructions: emails, calendar, contacts, tasks, files, weather, places, routes, web search, and even the MCP servers you add yourself.
To connect these roles, I chose LangGraph, a library that describes a process as a graph: steps, and rules that say which one comes next. Your message follows this graph from start to finish.
How it works
- Sorting. The router reads your message and decides whether it's conversation or a request for action, and which domains are involved. “Thanks, that was perfect” goes straight to the answer. The Friday dinner goes to the planner, with the calendar, contacts and emails.
- The plan. The planner only receives the tools of those domains. It writes a plan: which steps, with which parameters, and which ones wait for another one's result.
- The check. Before any call, LIA checks this plan: an invented tool, a step waiting for another that can't be found, a value out of bounds. What can be fixed is fixed; what remains doubtful goes back to the planner.
- Execution. Independent steps start at the same time; the others wait for what they need. Here: the calendar first, then all the guests in parallel, then the email draft, which you approve before it's sent.
- The little extra. Once the results are back, LIA checks whether some information is missing that it can simply read. If an email proposes a meeting on Thursday, it can glance at your Thursday calendar. It can also suggest an action to you, without carrying it out.
- The answer. A final role gathers what happened and writes it to you, separating what succeeded from what failed.
Two ways of working
This circuit is Pipeline mode: plan first, execute after. It's the most economical and the most predictable, and it's the default. But some questions can't be planned in advance. “What should we do this weekend?” depends on what LIA will discover along the way. The chat menu lets you choose ReAct, which reads each result before continuing, or Automatic, which chooses the engine for each request. Both modes share the same memory and the same confirmations, and meet at the same answer step.
A thread that doesn't get lost
After each step, the conversation's state is saved in the database (PostgreSQL). When LIA is waiting for your approval, it picks up exactly where it left off as soon as you answer, as long as the question hasn't expired. If you close the tab, the answer carries on on the server and waits for you when you come back. And when a conversation gets very long, LIA summarizes its beginning for its own use, without erasing anything from the history you see.
The limits
Sorting can get it wrong. When the router is truly in doubt, it answers you without acting, and rephrasing is often enough. Pipeline mode fixes its plan before seeing the results: if a step fails, it tells you, without improvising another path. And a domain only exists for LIA if its service is connected: without your calendar, no plan can read it.
The full circuit is described on the technical page.
Read more: A plan before acting: how LIA prepares and checks your multi-step requests; Pipeline or ReAct: two ways for LIA to handle your request.